


Nvidia Nemotron 3.5 Bolt: 74B Agent Model Runs Locally on Laptops Within 24GB Memory
 16 October 2026 05:34 PM
Abstract: Nvidia’s new Nemotron 3.5 family includes a 24GB 74B Bolt MoE model optimized for local laptop AI agents, alongside a powerful 120B multimodal Super VL for enterprise workflows.
Nvidia rolled out its latest Nemotron 3.5 AI lineup, headlined by Nemotron 3.5 Super VL and two compact Bolt models designed for local agent tasks. The flagship Super VL is a 120B multimodal model built for enterprise agents, while the Bolt variants target laptop-based coding, research and conversational AI.
Super VL retains 120B total parameters with 12B active during inference and a 1-million-token context window. Building on the earlier Nemotron 3 Super, it adds image and video input support for visual document analysis, chart interpretation and OCR. Benchmark results against rival open models such as Qwen are mixed. It achieves strong scores on scientific reasoning and terminal tasks yet falls slightly behind competitors on software engineering benchmarks. The model uses a hybrid Mamba-2, attention and MoE architecture paired with speculative decoding, boosting text generation speed up to 2.3 times on DGX Spark.
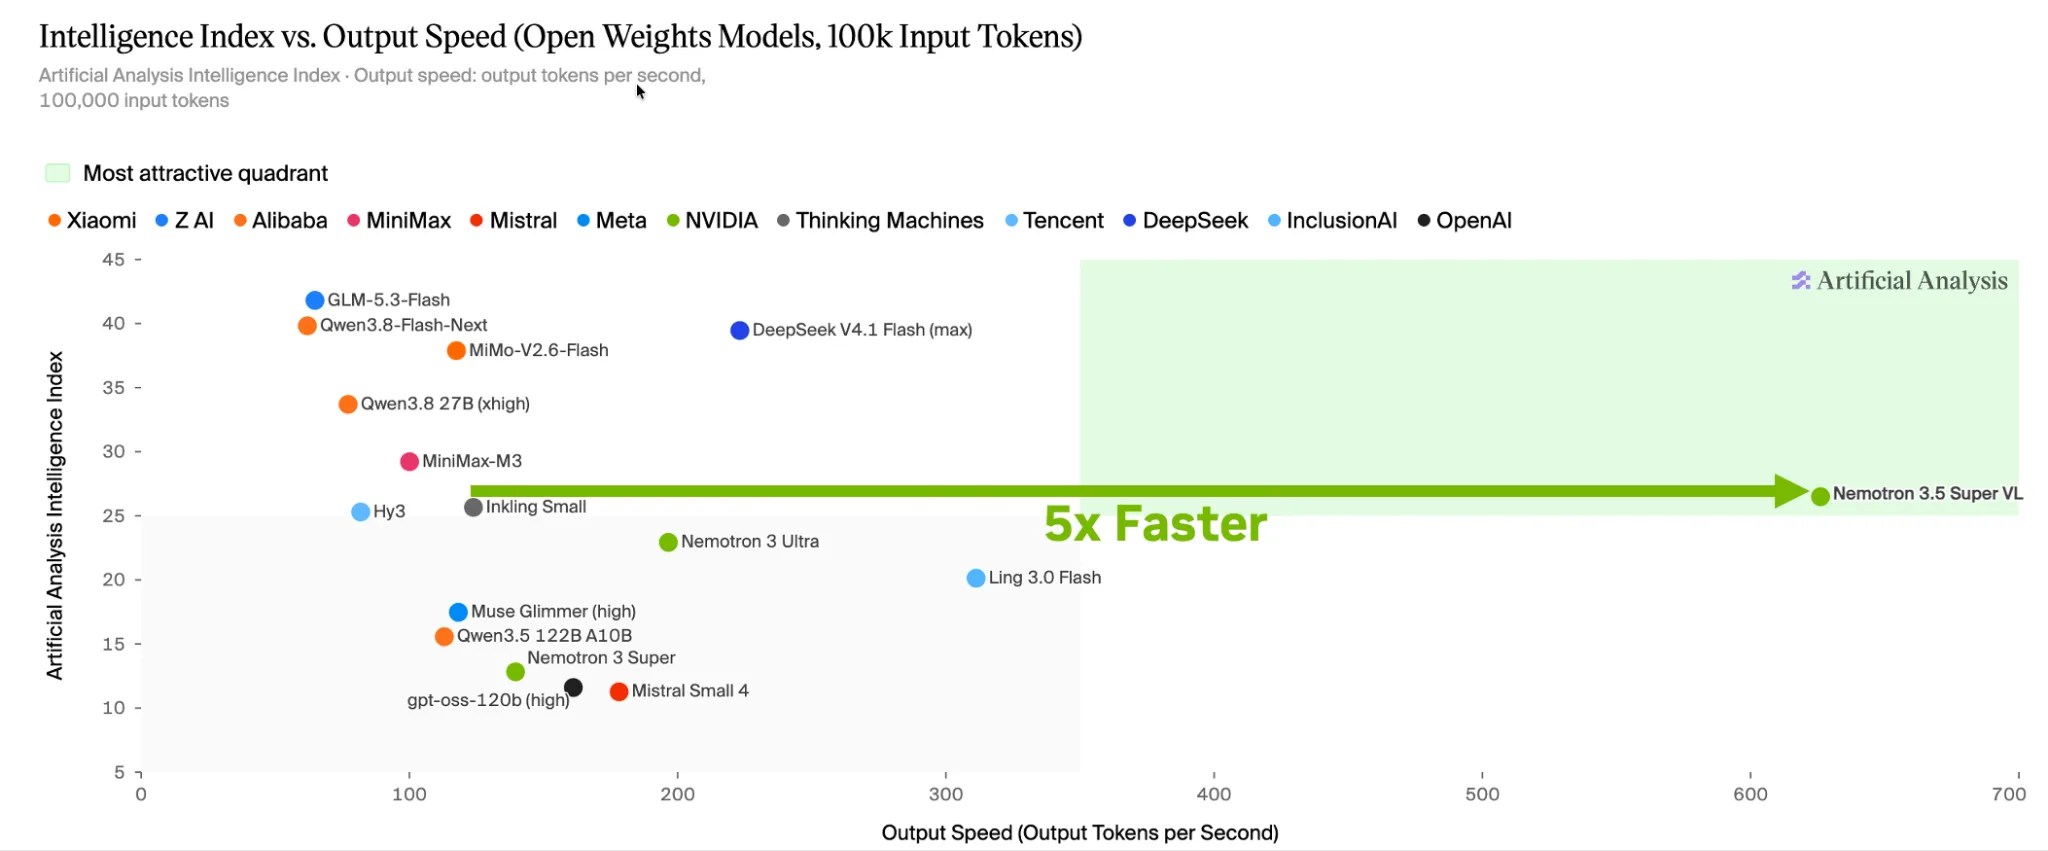
The most notable release is Nemotron 3.5 Bolt 74B-A9B, compressed via 2-bit quantization to fit within 24GB of VRAM. This MoE model activates only 9B parameters at runtime and outperforms Qwen and Gemma on agent benchmarks. It supports popular local AI frameworks including llama.cpp, Ollama and vLLM for RTX Spark laptops. A smaller Nemotron 3.5 Bolt E4B 4GB model will launch later this month for lightweight conversational and embedded agents on GeForce RTX and Jetson hardware.
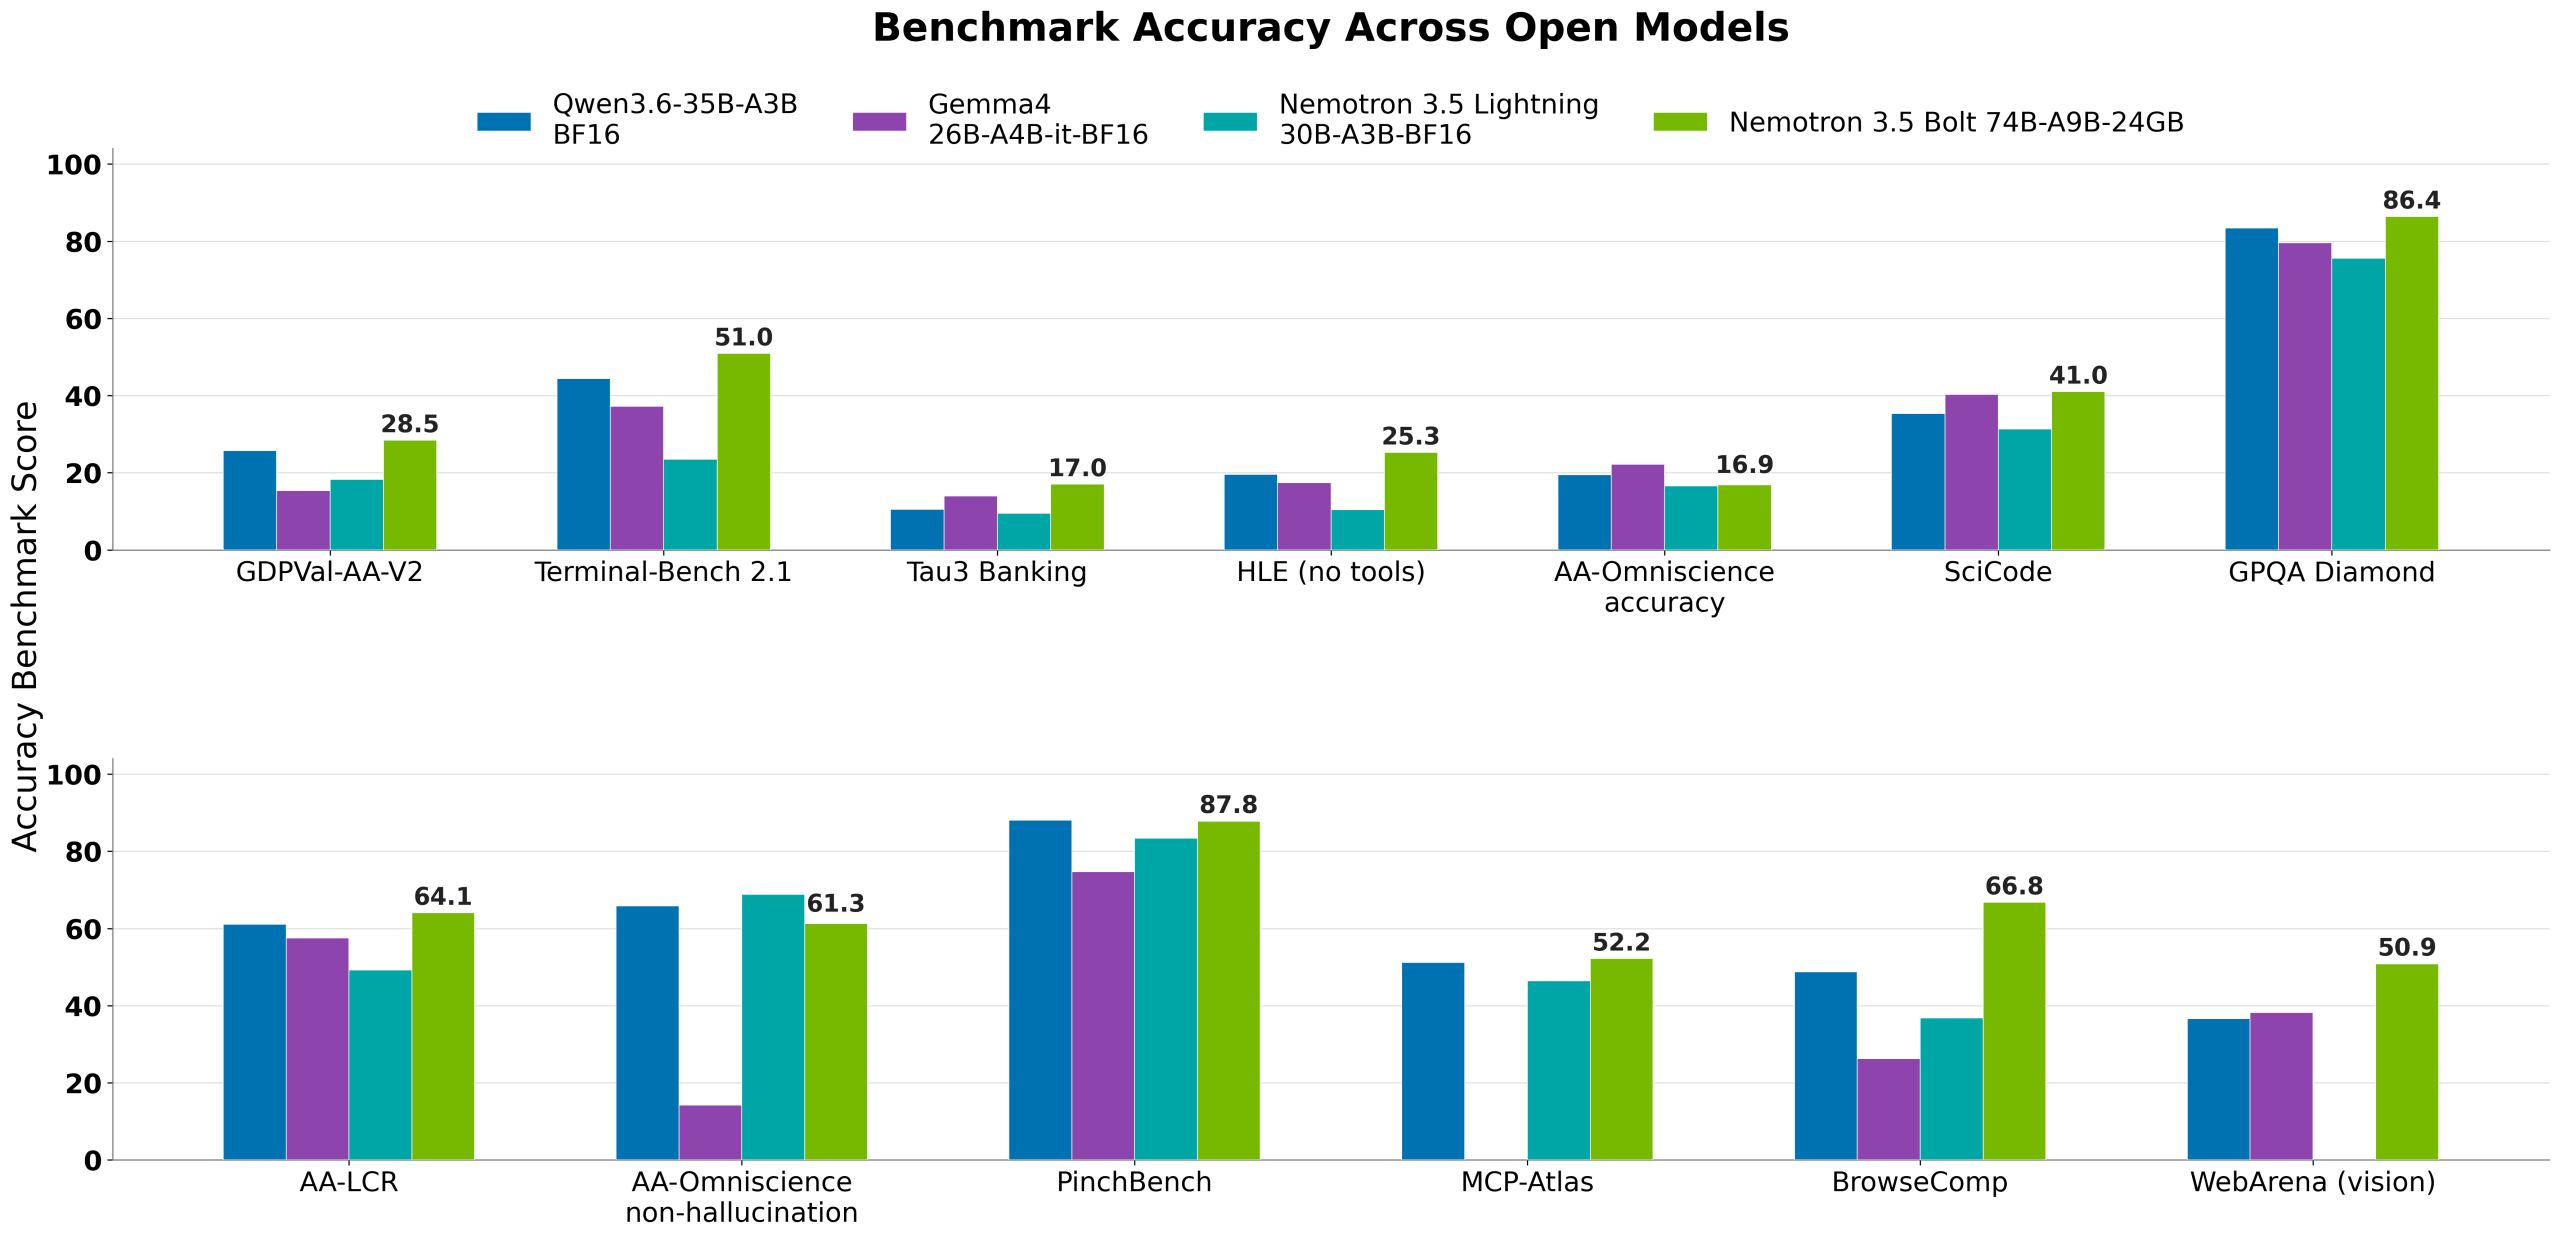
All three new models prioritize inference speed and efficiency. The two larger versions are available immediately, while the 4GB Bolt variant remains pending. Nvidia positions the Bolt series to handle multi-step reasoning, tool calling and web browsing directly on consumer devices without cloud access.