


Summary:Researchers at the University of Southern California have developed a spatially aware Hyperdimensional Computing (HDC) system accelerated by FPGA technology, overcoming major speed limitations of traditional CPU and GPU implementations. The new architecture achieves high image recognition accuracy with up to 1300× faster processing than CPUs and 60× faster than GPUs, enabling real-time AI applications in robotics, autonomous systems, and medical imaging.
Recent research from the University of Southern California, led by Dhruv Parikh, Jebacyril Arockiaraj, and Viktor Prasanna, addresses key bottlenecks limiting Hyperdimensional Computing (HDC) in real-time applications. Although effective for machine learning and image processing, HDC remains inefficient on CPUs and GPUs. This work integrates a spatially aware encoding algorithm with FPGA acceleration to overcome these limitations.
Spatially Aware, Patch-Based HDC Image Encoding
The method encodes local image patches into hypervectors that capture both feature and spatial information, then combines them via binding, permutation, and bundling. This improves robustness and spatial sensitivity while preserving HDC simplicity. It achieves 95.67% accuracy on MNIST and 85.14% on Fashion-MNIST, outperforming prior HDC methods and resembling CNN-style local feature extraction.
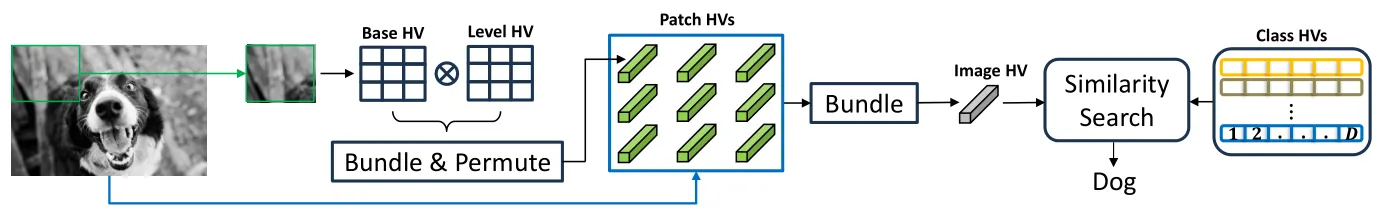
Overall patch-based HDC encoding pipeline (during inference).
FPGA-Based Accelerator for HDC Processing
A custom accelerator on an Alveo U280 FPGA exploits hypervector-level and patch-level parallelism through a patch processor array, global adder tree, and similarity engine. It achieves 0.09 ms latency, delivering up to 1300× speedup over CPUs and 60× over GPUs, enabling real-time performance.
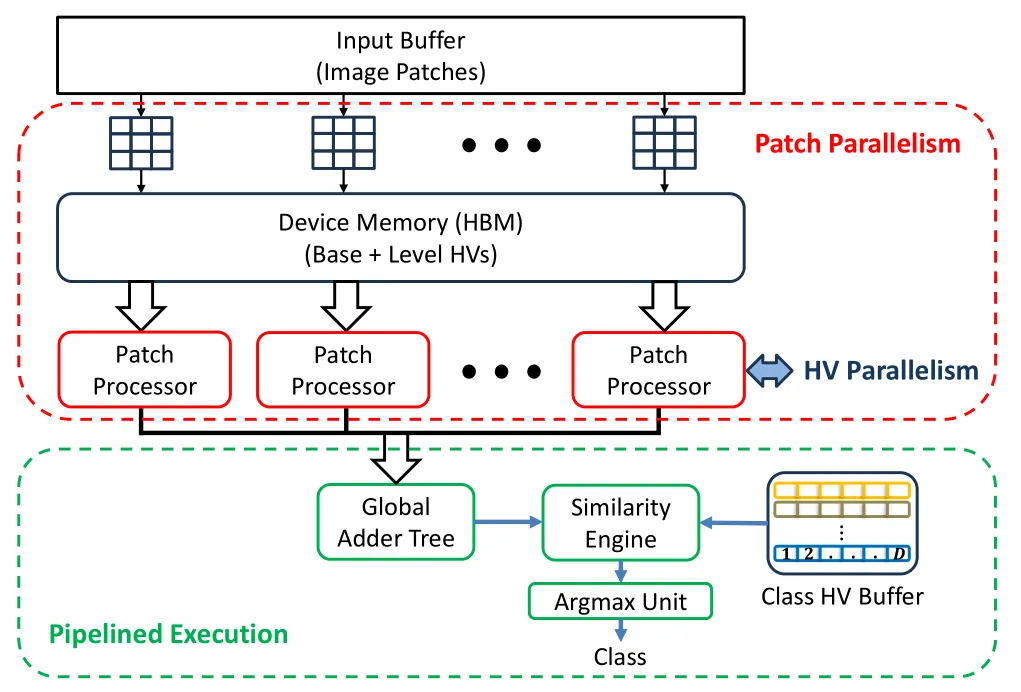
The accelerator architecture exposes both patch-level and hypervector-level parallelism using multiple patch processors, a global adder tree,similarity engine, and a lightweight argmax unit.
Evaluation and Hardware Efficiency
The FPGA implementation outperforms optimized PyTorch baselines in latency and throughput while maintaining competitive accuracy. Ablation studies reveal trade-offs among patch size, hypervector dimension, and efficiency, while online similarity-guided updates further improve accuracy.
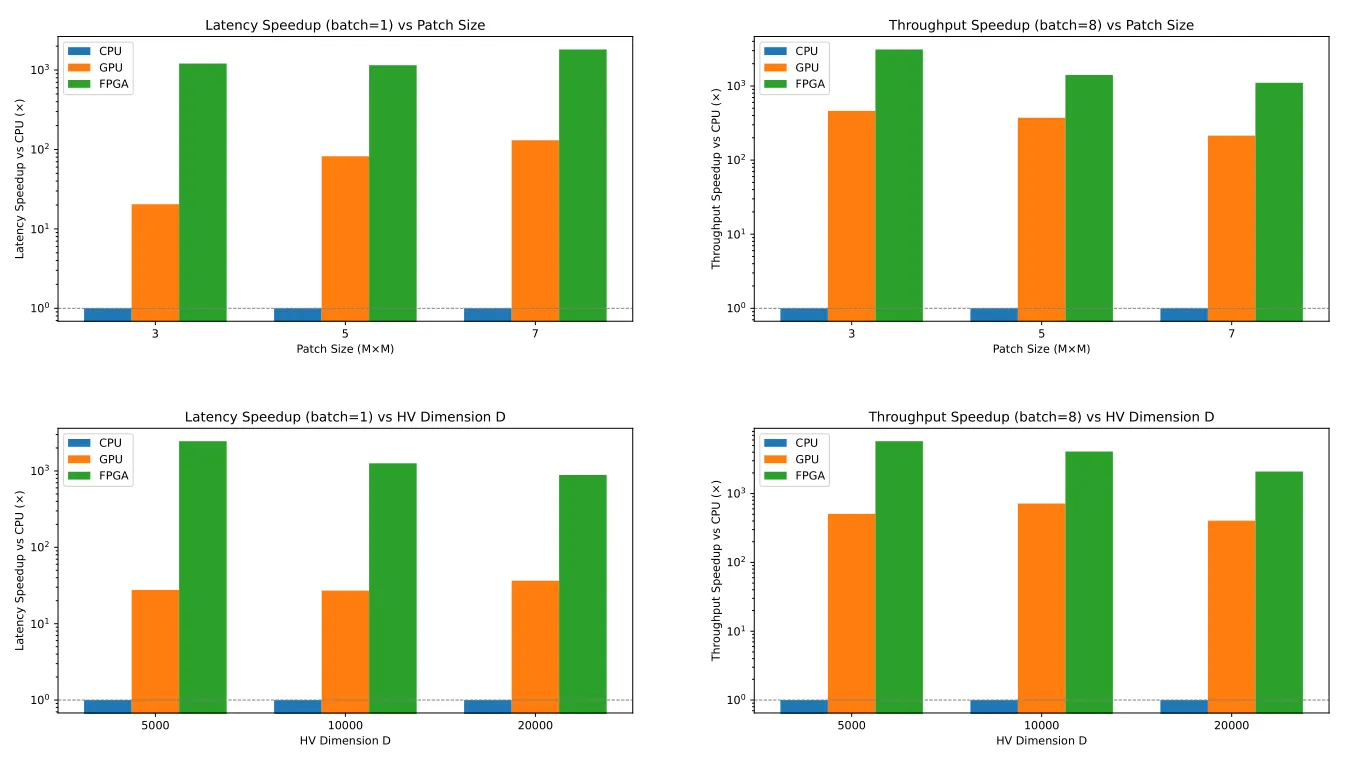
Latency and throughput speedup relative to the CPU baseline. (Top) Effects of patch size using D=10,000.(Bottom) Scaling with hypervector dimension D.CPU speedup baseline is 1×.
Future Research Directions
Future work includes scaling to more complex datasets and applications such as autonomous driving, robotics, and medical imaging, improving FPGA energy efficiency, and exploring hybrid HDC–deep learning models.
This work demonstrates that combining spatially aware encoding with FPGA acceleration enables fast, accurate, and practical real-time HDC systems.

