


Summary: SubQ, a new AI model, sets a record with a 12 million token context window, delivering faster and more cost-efficient long-text and code processing. Its linear attention architecture outperforms leading Transformer-based models, potentially reshaping long-context AI applications.
A new long-context artificial intelligence model named SubQ has set a new benchmark by supporting a 12 million token context window, surpassing the limits of traditional Transformer architectures. Officially launched on May 5, 2026, the model delivers significant speed and cost improvements for ultra-long text and code processing, challenging mainstream large language models.
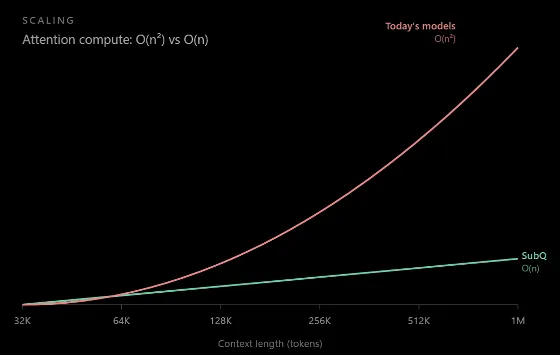
Built on a proprietary Subquadratic Sparse Attention (SSA) architecture, SubQ reduces Transformer computation from quadratic O(n²) to linear O(n) complexity, resolving the high-compute bottlenecks that have long constrained long-context AI applications.
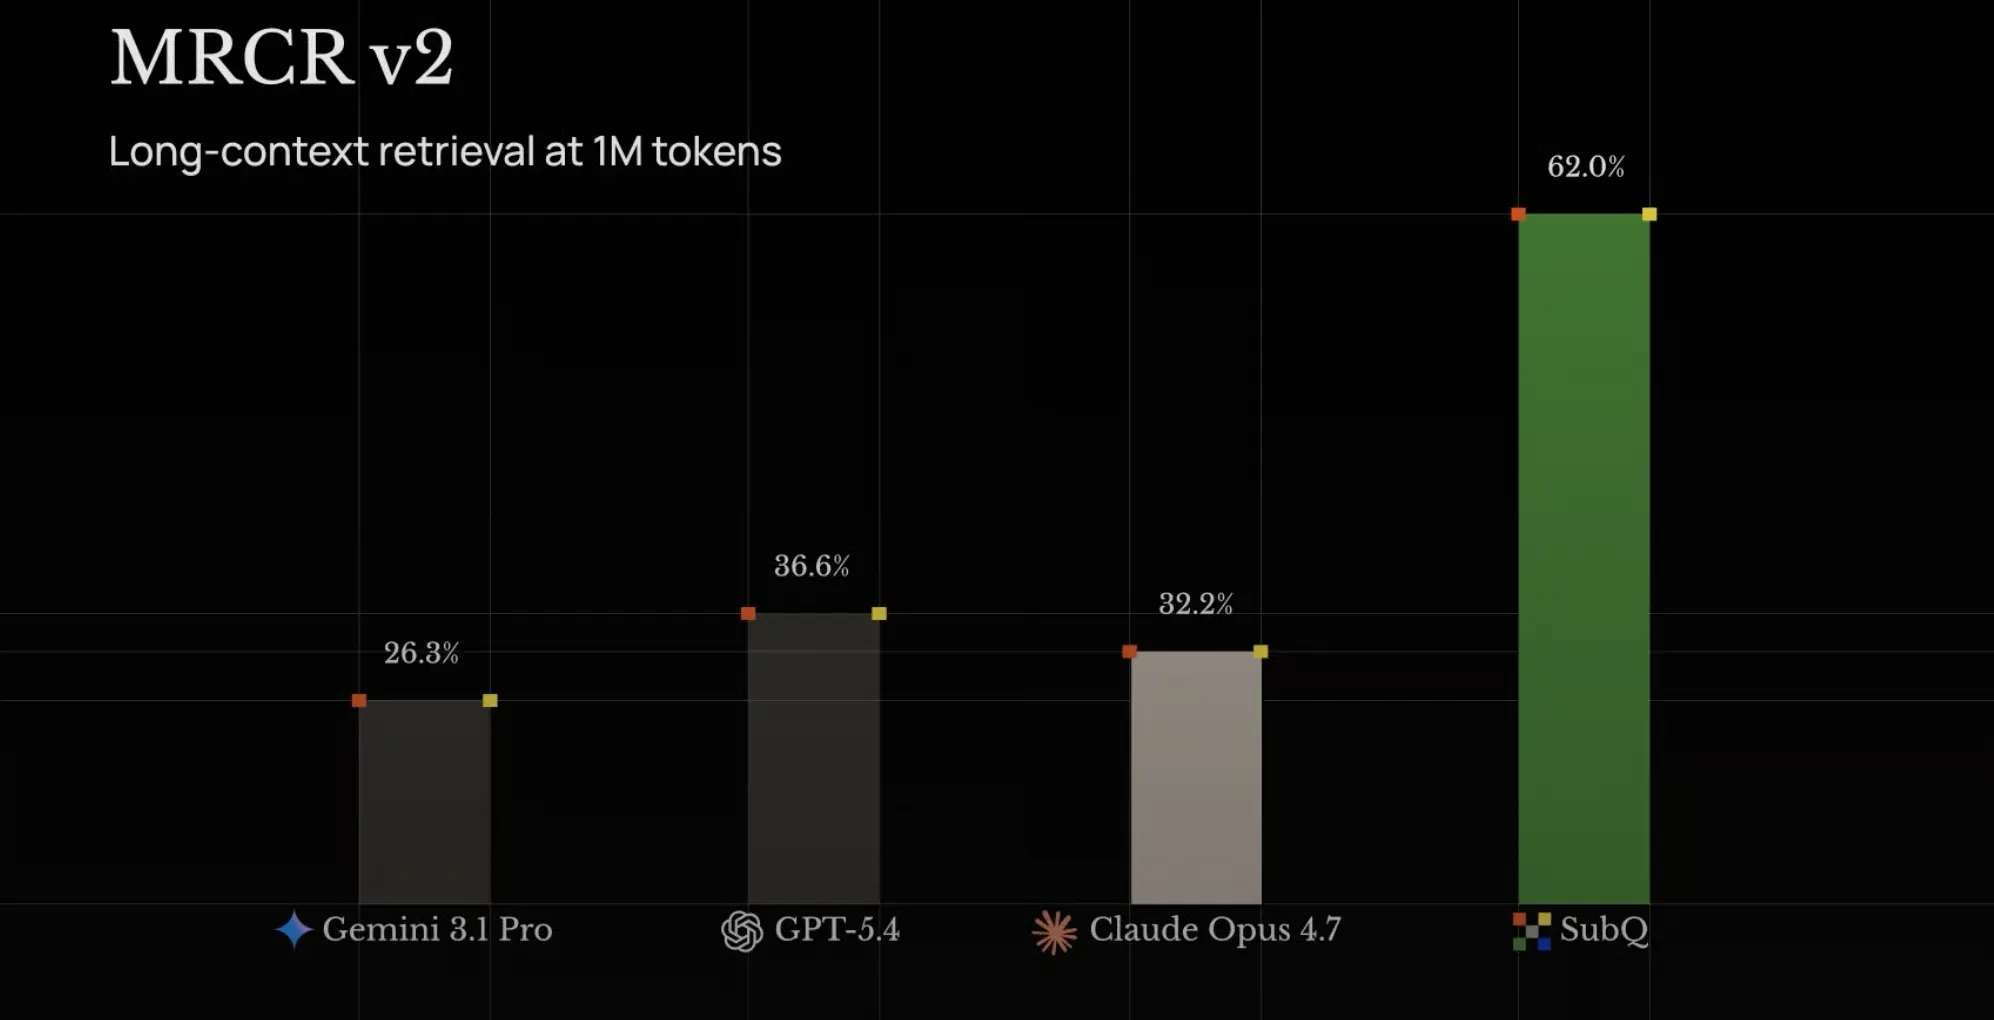
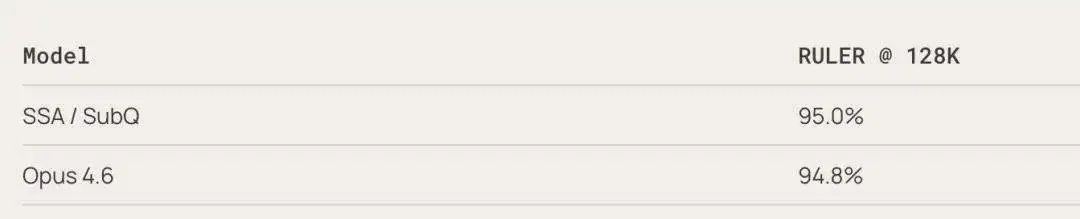
Independent benchmarks on the RULER 128K dataset show SubQ achieves 95.0% retrieval accuracy, outperforming leading models such as Claude Opus 4.6, GPT, and Gemini in multi-needle long-context retrieval tasks. When processing 1 million-token inputs, SubQ runs 52 times faster than conventional FlashAttention solutions, reduces computational overhead by 63%, and lowers operational costs to roughly 5% of comparable models.
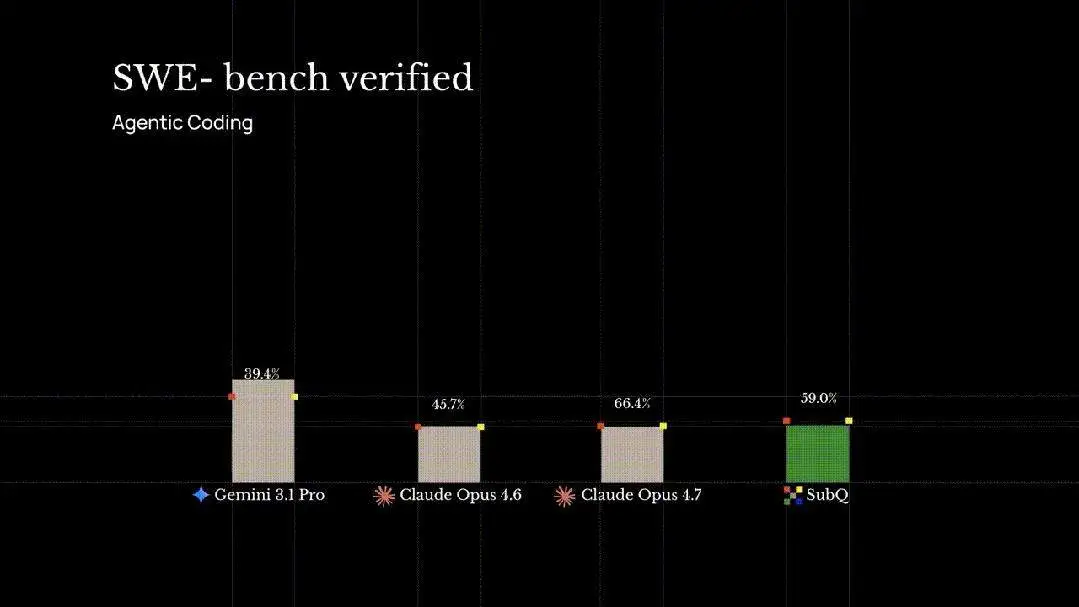
The development team, composed of researchers with experience at top AI labs and universities, has released three beta products:
SubQ API for scalable long-context inference
SubQ Code for full-codebase analysis
SubQ Search for in-depth long-document research
These tools are aimed at enterprise knowledge bases, large-scale log parsing, and code iteration, forming an initial framework for commercial long-context AI services.
Despite promising performance, the model faces scrutiny. The full technical paper has not yet been published, leaving architectural innovations and performance claims pending comprehensive third-party verification. Analysts note that if SubQ’s linear attention efficiency and long-context stability are validated in large-scale deployment, it could disrupt nearly a decade of Transformer dominance, reshaping the cost and efficiency paradigm for enterprise-grade long-content AI.

